
chromium-screenshots
Enables AI agents to capture pixel-perfect screenshots with synchronized DOM data and quality metrics, supporting auth injection and MCP integration for vision AI tasks.
README
chromium-screenshots
The missing screenshot service for Vision AI & Auth. Inject auth. Extract DOM. Zero-drift capture. Pixel-perfect Chromium.


⚡ Why this exists
Taking screenshots for Vision AI is hard. If you take a screenshot and then scrape the HTML separately, the page state drifts. Elements move. Popups appear. Your bounding boxes don't match the pixels.
chromium-screenshots guarantees Zero-Drift. It extracts the DOM coordinates (ground truth) and the screenshot (pixels) from the exact same render frame.
Visual Proof
| Feature | Standard Tools | chromium-screenshots |
|---|---|---|
| Data Extraction | ❌ Image Only | ✅ Image + DOM + Bounding Boxes |
| Quality Control | ❌ None (hope it loaded) | ✅ Quality Score (Good/Low/Poor) |
| Auth Injection | ❌ Cookies only | ✅ Cookies + LocalStorage + SessionStorage |
| AI Integration | ❌ Manual API calls | ✅ Native MCP Server (Claude/Gemini) |
| SPA Support | ❌ Fails on hydration | ✅ Waits for selectors/network idle |
🤖 Standardized AI Integration
This tool is a "visual cortex" for your AI agents. It implements the Model Context Protocol (MCP), allowing tools like Claude Desktop to natively control the browser.
screenshot: Returns base64 data for immediate analysis ("What does this button say?").screenshot_to_file: Saves to disk to preserve context window tokens.extract_dom: Returns text + coordinates for ground-truth verification.
Comparison with Alternatives
While many tools exist for browser automation and content extraction, chromium-screenshots is specifically designed to provide high-fidelity observation for AI agents, rather than just raw data or static images.
| Tool Category | Examples | Screenshot | Structural Data | Quality Metric | Primary Focus |
|---|---|---|---|---|---|
| Agent Observation | This Repo | ✅ | ✅ (Atomic DOM) | ✅ | AI Reliability & Context |
| LLM RAG Scrapers | Firecrawl, Jina | ✅ | ❌ (Markdown) | ❌ | Text extraction for reading |
| Screenshot APIs | ScreenshotOne, ApiFlash | ✅ | ❌ (HTML) | ⚠️ (Basic) | Marketing & Archiving |
| Performance Audit | Lighthouse CI | ✅ | ✅ (Full DOM) | ✅ | Speed & SEO Audits (Slow) |
| Visual Testing | Percy, Chromatic | ✅ | ✅ (Snapshot) | ✅ | Regression Testing (Diffs) |
🚀 Quick Start
Docker (Recommended)
Run the containerized service. No dependencies required.
docker compose up -d
The API is now active at
http://localhost:8000.
Python (Local)
pip install -r requirements.txt
playwright install chromium
uvicorn app.main:app --reload
💡 Common Recipes
1. Vision AI Ground Truth
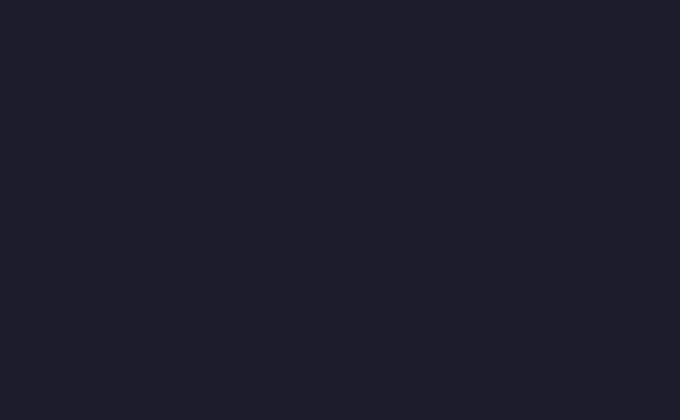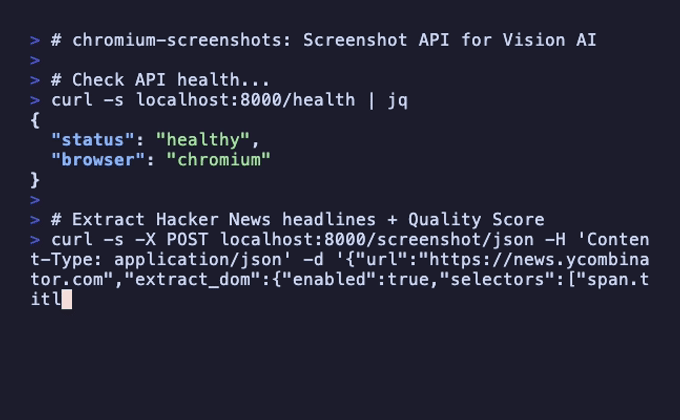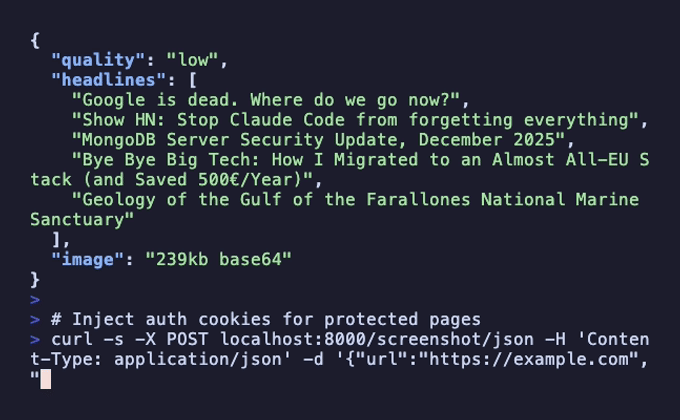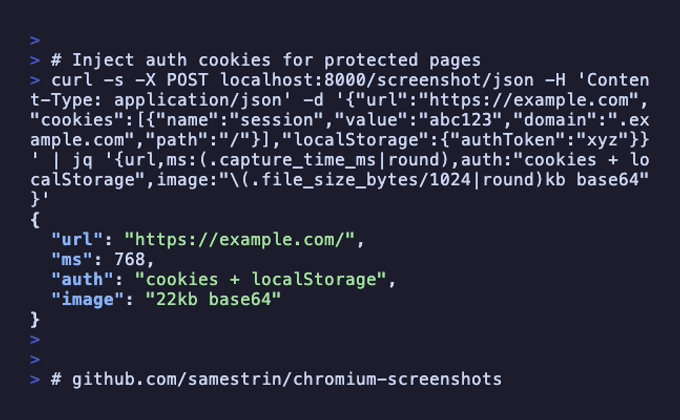
Capture screenshot + DOM data + Quality Score in one call.
curl -X POST "http://localhost:8000/screenshot" \
  -H "Content-Type: application/json" \
  -d '{
    "url": "https://news.ycombinator.com",
    "extract_dom": {
      "enabled": true,
      "selectors": ["span.titleline > a"],
      "max_elements": 50
    }
  }' -o hn_capture.png
2. The "Impossible" Auth Shot
Inject localStorage to capture authenticated dashboards (Wasp/Firebase).
curl -X POST "http://localhost:8000/screenshot" \
  -H "Content-Type: application/json" \
  -d '{
    "url": "https://app.example.com/dashboard",
    "localStorage": {
      "wasp:sessionId": "secret_session_token",
      "theme": "dark"
    },
    "wait_for_selector": ".dashboard-grid"
  }' -o dashboard.png
3. Vision AI Optimization
Get quality metrics and model compatibility hints for Vision AI integrations.
curl -X POST "http://localhost:8000/screenshot/json" \
  -H "Content-Type: application/json" \
  -d '{
    "url": "https://news.ycombinator.com",
    "extract_dom": {
      "enabled": true,
      "include_metrics": true,
      "include_vision_hints": true,
      "target_vision_model": "claude"
    }
  }' | jq '{quality: .dom_extraction.quality, hints: .vision_hints}'
📚 Documentation
Detailed references for core features:
- API Reference - Full endpoint and parameter guide.
- DOM Extraction - How to use ground-truth element coordinates.
- Quality Assessment - Understanding extraction quality and warnings.
- MCP Server - Integration with Claude Desktop & AI agents.
🧠 How It Works
The Zero-Drift Flow:
- Inject Auth: Set
cookies&localStorage. - Navigate: Load page and wait for
networkidle. - Freeze: Pause execution.
- Extract: Scrape DOM positions & Text (JS evaluation).
- Audit: Run Quality Detection engine (count elements, check visibility).
- Capture: Take screenshot.
- Return: Send Image + JSON together.
sequenceDiagram
    participant U as 👤 User / Agent
    participant A as ⚡ API / MCP
    participant B as 🕸️ Chromium
    participant Q as 🔍 Quality Engine

    U->>A: POST /screenshot (extract_dom=true)
    A->>B: Create Context & Inject Auth
    B->>B: Navigate & Wait

    rect rgb(30, 30, 30)
        note right of B: Critical Section
        B->>B: Extract DOM (JS)
        B->>Q: Assess Quality
        Q-->>B: Quality: GOOD
        B->>B: Capture Pixels
    end

    B-->>A: Result (Image + Metadata)
    A-->>U: Return
License
推荐服务器

Baidu Map
百度地图核心API现已全面兼容MCP协议,是国内首家兼容MCP协议的地图服务商。

Playwright MCP Server
一个模型上下文协议服务器,它使大型语言模型能够通过结构化的可访问性快照与网页进行交互,而无需视觉模型或屏幕截图。

Magic Component Platform (MCP)
一个由人工智能驱动的工具,可以从自然语言描述生成现代化的用户界面组件,并与流行的集成开发环境(IDE)集成,从而简化用户界面开发流程。

Audiense Insights MCP Server
通过模型上下文协议启用与 Audiense Insights 账户的交互,从而促进营销洞察和受众数据的提取和分析,包括人口统计信息、行为和影响者互动。

VeyraX
一个单一的 MCP 工具,连接你所有喜爱的工具:Gmail、日历以及其他 40 多个工具。

graphlit-mcp-server
模型上下文协议 (MCP) 服务器实现了 MCP 客户端与 Graphlit 服务之间的集成。 除了网络爬取之外,还可以将任何内容(从 Slack 到 Gmail 再到播客订阅源)导入到 Graphlit 项目中,然后从 MCP 客户端检索相关内容。

Kagi MCP Server
一个 MCP 服务器,集成了 Kagi 搜索功能和 Claude AI,使 Claude 能够在回答需要最新信息的问题时执行实时网络搜索。

e2b-mcp-server
使用 MCP 通过 e2b 运行代码。

Neon MCP Server
用于与 Neon 管理 API 和数据库交互的 MCP 服务器

Exa MCP Server
模型上下文协议(MCP)服务器允许像 Claude 这样的 AI 助手使用 Exa AI 搜索 API 进行网络搜索。这种设置允许 AI 模型以安全和受控的方式获取实时的网络信息。