
mcpgrade
Grades MCP servers on agent usability (A–F) — description quality, schema design, tool naming and token cost, the properties that decide whether a model picks the right tool. Benchmarked across 36 popular servers; a third scored D or F.
README
mcpgrade
Lighthouse for MCP servers. Your server can be 100% spec-compliant and still fail agents — vague descriptions, token-bloated schemas, confusable tool names. mcpgrade scores what compliance checkers can't: whether an LLM can actually use your tools.
npx mcpgrade https://your-server.example.com/mcp   # streamable HTTP
npx mcpgrade --stdio "node ./my-server.js"          # local stdio server
npx mcpgrade --snapshot tools.json                  # saved tools/list output

npx mcpgrade https://mcp-us.example.com/mcp/streamable \
  --header "Authorization: Bearer $TOKEN"           # authenticated remote server
Zero config. No API key. Report in seconds.
What it checks
| Category | Weight | Examples |
|---|---|---|
| Descriptions | 30% | missing/too-short descriptions, undocumented params, placeholder text, duplicate descriptions |
| Schema design | 30% | missing types, no required array, additionalProperties: true, prose-instead-of-enum, deep nesting |
| Naming | 15% | confusable names (get_user vs get_users), generic verbs (process), mixed conventions |
| Token cost | 15% | catalog total budget, per-tool budget — agents pay your schema on every request |
| Consistency | 10% | catalog-wide uniformity; with --probe, live checks that error messages help the model self-correct |
Every finding comes with a concrete fix. Scores are density-normalized: 3 broken tools out of 3 is an F; 3 out of 30 is a dent.
Example
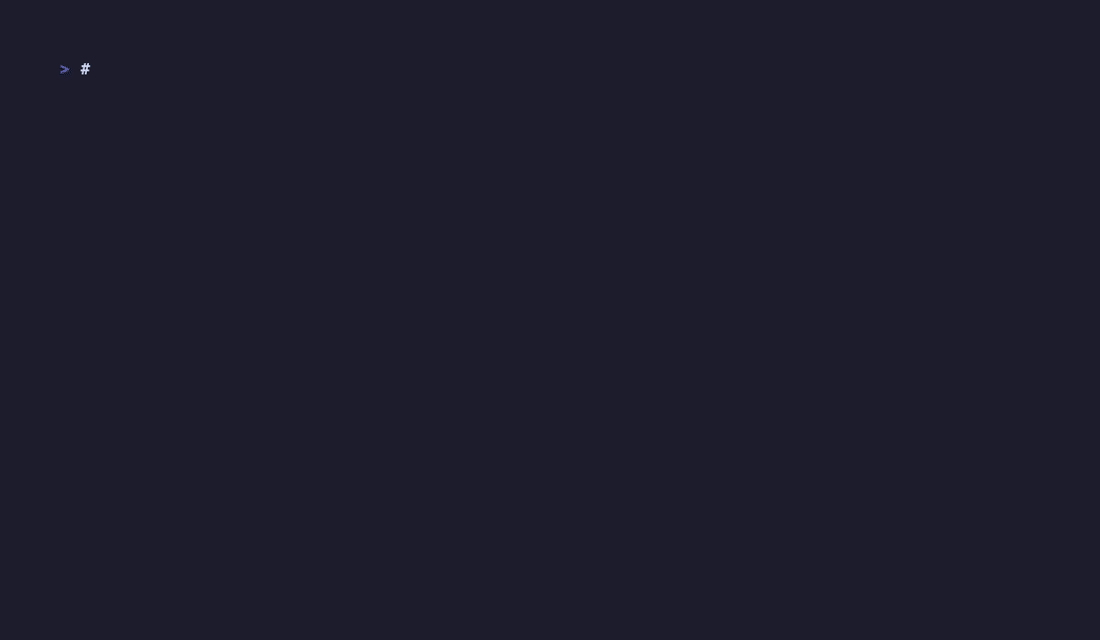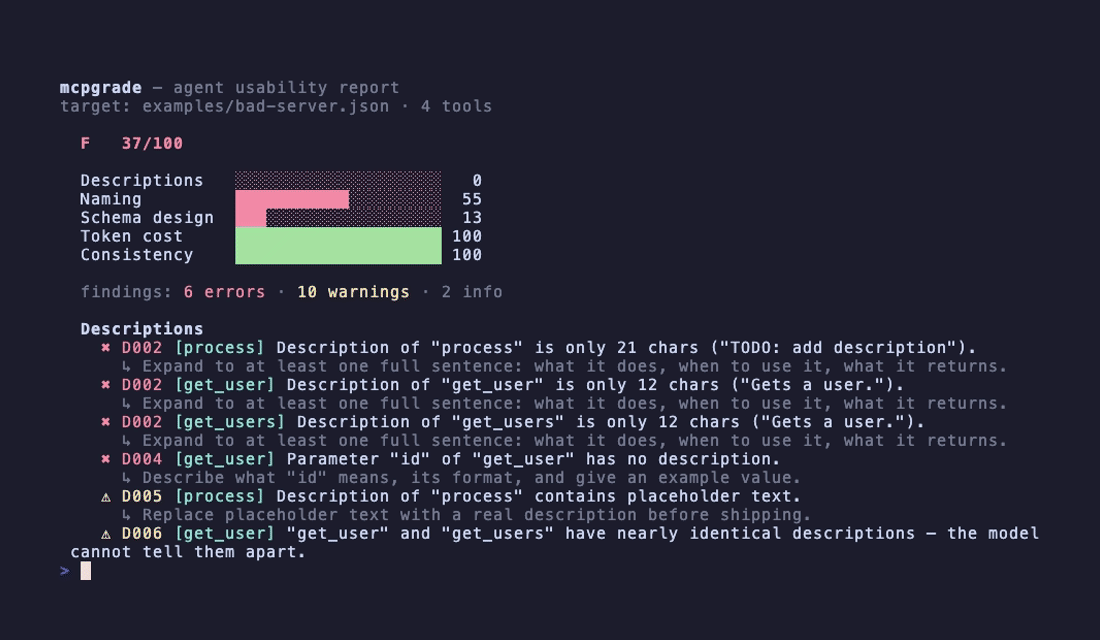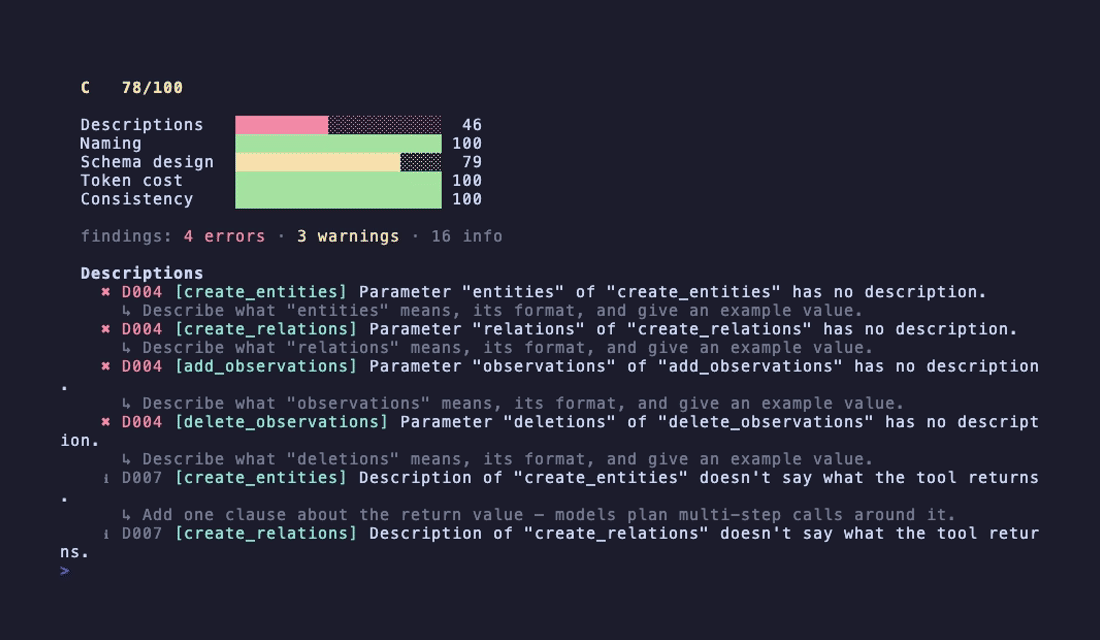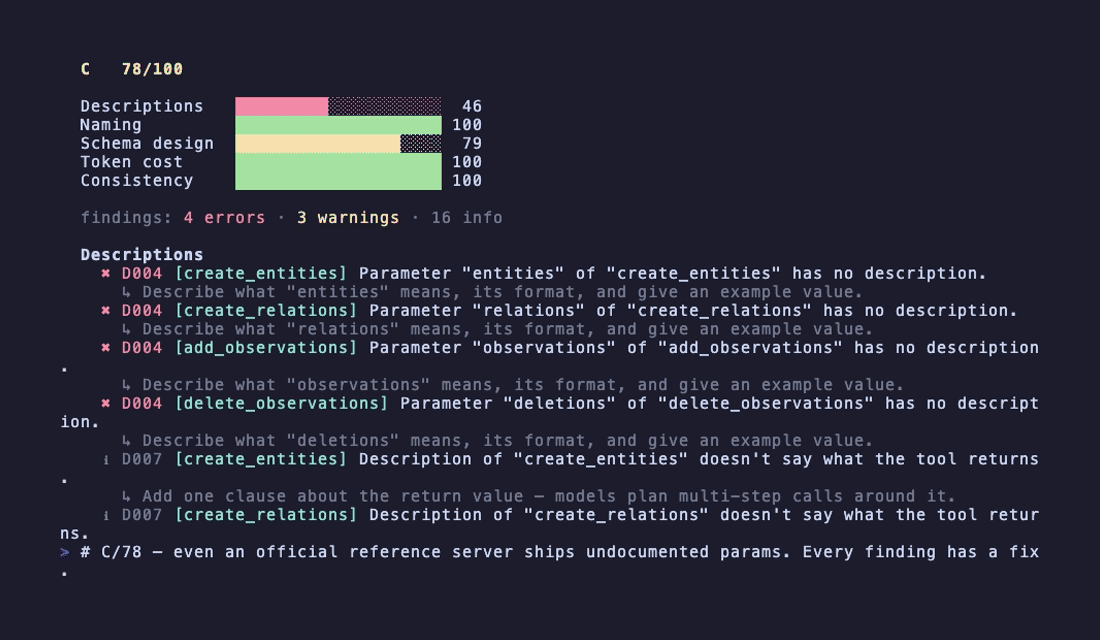
mcpgrade — agent usability report
target: examples/bad-server.json · 4 tools

  F   37/100

  Descriptions   ░░░░░░░░░░░░░░░░░░░░   0
  Naming         ███████████░░░░░░░░░  55
  Schema design  ███░░░░░░░░░░░░░░░░░  13
  Token cost     ████████████████████ 100
  Consistency    ████████████████████ 100

  findings: 6 errors · 10 warnings · 2 info

  Descriptions
    ✖ D002 [get_user] Description of "get_user" is only 12 chars ("Gets a user.").
      ↳ Expand to at least one full sentence: what it does, when to use it, what it returns.
    ...
MCP server mode
mcpgrade also runs as an MCP server, so an agent can grade other servers on your behalf:
claude mcp add mcpgrade -- npx -y mcpgrade serve
Or add it manually:
{
  "mcpServers": {
    "mcpgrade": { "command": "npx", "args": ["-y", "mcpgrade", "serve"] }
  }
}
Three tools, deliberately: grade_mcp_server, explain_rule, list_grading_rules.
Security. In serve mode the target string is chosen by a model, so local launch
commands are restricted to an allowlist (npx, node, python, python3, uv,
uvx, deno, bun, docker). URLs and .json snapshots are always allowed. The
CLI has no such restriction.
Dogfooding. The serve catalog is graded by mcpgrade in CI and must score an A with zero errors (test/serve.test.ts) — if a change drops the grade, the fix is the catalog, not the threshold. Current self-score:
A 96/100 3 tools · 0 errors · 1 warning
The one warning is a rule I disagree with on this catalog: S005 flags target
for describing a fixed value set in prose without an enum. The prose lists
permitted command prefixes for an otherwise free-form string, so an enum is not
expressible. Left in place rather than suppressed — the ruleset is opinionated by
design, and disagreements belong in the open (#10).
Authenticated remote servers
Most hosted MCP servers require a bearer token. Pass headers with --header
(repeatable), or set MCPGRADE_HEADERS="Authorization: Bearer …; X-Tenant: acme":
npx mcpgrade https://your-host/mcp --header "Authorization: Bearer $TOKEN"
Streamable HTTP is tried first, with an automatic SSE fallback for servers on the
older transport. mcpgrade only calls tools/list — it never invokes a tool unless
you pass --probe.
Header values are treated as secrets: they go to the transport and nowhere
else — not the report, not --json output, not the eval envFingerprint. MCP
serve mode accepts no headers at all, since there the target is chosen by a model
and a model has no business handing out credentials.
CI
mcpgrade <target> --json                # machine-readable
mcpgrade <target> --fail-on error       # exit 1 on errors — gate your PRs
mcpgrade <target> --disable S008,N001   # tune rules
mcpgrade rules                          # list all rules
Why
I integrate first-party and third-party MCP connectors into a production AI agent for a living. Most MCP servers fail agents in the same ten ways — none of which show up in a spec compliance check. So I wrote the linter I wished server authors had run before shipping.
mcpgrade vs mcp-lint
Different tools, different questions. mcp-lint checks whether your tool schemas parse correctly across clients (Claude, Cursor, OpenAI strict mode, ...) — syntax-level compatibility. mcpgrade measures whether a model can actually use your tools — description quality, naming confusion, token economics, and live LLM tool-selection accuracy. A server can pass mcp-lint cleanly and still score an F here, and vice versa. They compose well: lint for compatibility, grade for usability. Full side-by-side with concrete outputs: docs/comparison.md.
Roadmap
- [x] v0.1 — static lint engine, 24 rules, A–F scoring
- [x] v0.2 —
--eval: LLM-powered live testing — synthetic task generation, blind tool selection, argument validation, refusal accuracy, confusion pairs. Calibrated on real servers (methodology); costs ~$0.05–0.2 per server on Haiku. Bring your ownANTHROPIC_API_KEY, or any OpenAI-compatible endpoint via--eval-base-url(DeepSeek, OpenRouter, ...);--eval-mockruns offline. RespectsHTTPS_PROXY. - [x] v0.3 —
mcpgrade serve: runs as an MCP server so an agent can grade other servers (allowlisted launchers; the catalog is graded by mcpgrade in CI and must hold an A). PlusenvFingerprinton every eval result — catalog hash, model, temperature, prompt version, task policy — so two scores are comparably or visibly incomparable. - [x] Also shipped: GitHub Action for CI gating, and a public leaderboard of 36 popular servers.
- [ ] v0.4 — the failure taxonomy work, driven by reader feedback: four-outcome scoring, held-out task authoring, silent-vs-observable failures, cross-server collisions, multi-hop evaluation, rule-entailment dedup. Dynamic badges when the scoring model settles.
License
MIT
推荐服务器

Baidu Map
百度地图核心API现已全面兼容MCP协议,是国内首家兼容MCP协议的地图服务商。

Playwright MCP Server
一个模型上下文协议服务器,它使大型语言模型能够通过结构化的可访问性快照与网页进行交互,而无需视觉模型或屏幕截图。

Magic Component Platform (MCP)
一个由人工智能驱动的工具,可以从自然语言描述生成现代化的用户界面组件,并与流行的集成开发环境(IDE)集成,从而简化用户界面开发流程。

Audiense Insights MCP Server
通过模型上下文协议启用与 Audiense Insights 账户的交互,从而促进营销洞察和受众数据的提取和分析,包括人口统计信息、行为和影响者互动。

VeyraX
一个单一的 MCP 工具,连接你所有喜爱的工具:Gmail、日历以及其他 40 多个工具。

graphlit-mcp-server
模型上下文协议 (MCP) 服务器实现了 MCP 客户端与 Graphlit 服务之间的集成。 除了网络爬取之外,还可以将任何内容(从 Slack 到 Gmail 再到播客订阅源)导入到 Graphlit 项目中,然后从 MCP 客户端检索相关内容。

Kagi MCP Server
一个 MCP 服务器,集成了 Kagi 搜索功能和 Claude AI,使 Claude 能够在回答需要最新信息的问题时执行实时网络搜索。

e2b-mcp-server
使用 MCP 通过 e2b 运行代码。

Neon MCP Server
用于与 Neon 管理 API 和数据库交互的 MCP 服务器

Exa MCP Server
模型上下文协议(MCP)服务器允许像 Claude 这样的 AI 助手使用 Exa AI 搜索 API 进行网络搜索。这种设置允许 AI 模型以安全和受控的方式获取实时的网络信息。